DeepSeek V4.1 Flash Model Officially Released: Comprehensively Surpasses V4 Pro, Native Multimodal Visual Understanding, API Pricing Reduced
en.Wedoany.com Reported - On September 10, DeepSeek today officially released the DeepSeek V4.1 Flash model. This is the smallest model in its new model architecture series, featuring native multimodal visual understanding capabilities.
The design philosophy of the new model architecture is: higher capability ceiling, faster inference speed, greater throughput, and scalability to larger parameter models.
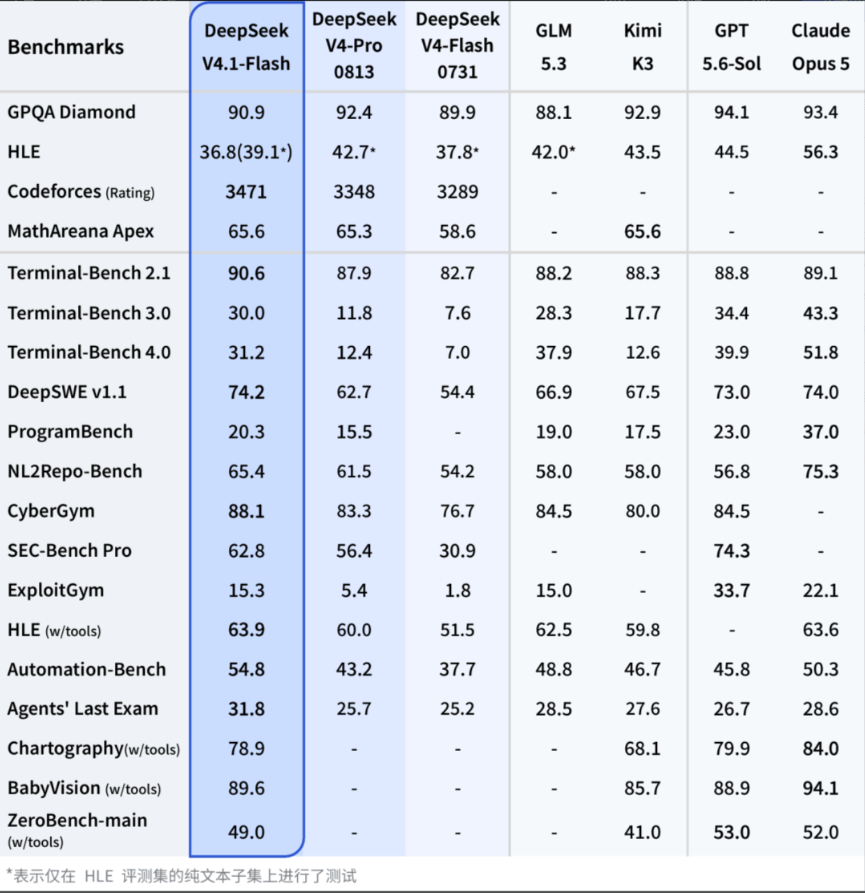
DeepSeek V4.1 Flash is a 552B parameter MoE model, adopting a brand-new Causal-Encoder-Decoder architecture with asymmetric input and output. Input activation is only 8B, output activation is 16B, and the cost is significantly lower than known models of the same size. Meanwhile, V4.1 Flash also adopts a new pre-training approach and has undergone larger-scale reinforcement learning post-training. In benchmark tests, it successfully surpassed the intelligence level of a range of flagship models, including DeepSeek V4 Pro.
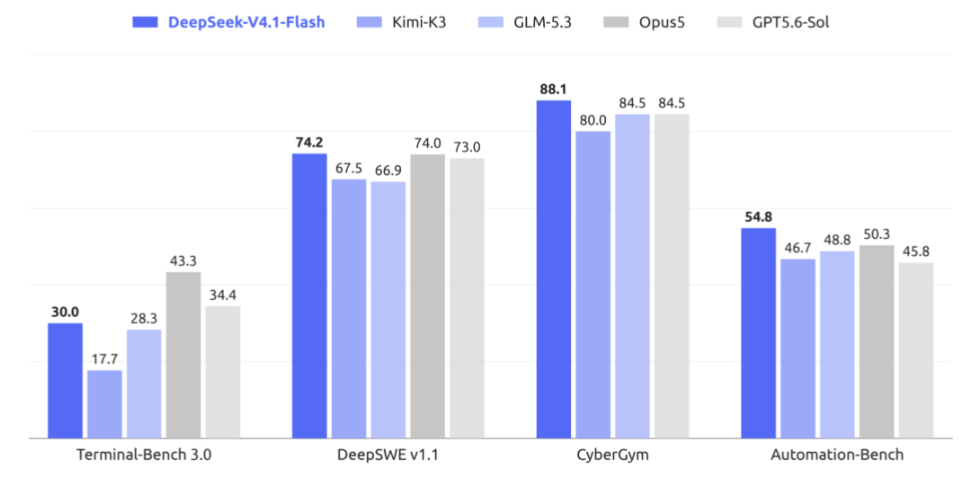
Performance comparison of DeepSeek-V4.1-Flash and mainstream frontier models on Agentic Benchmark
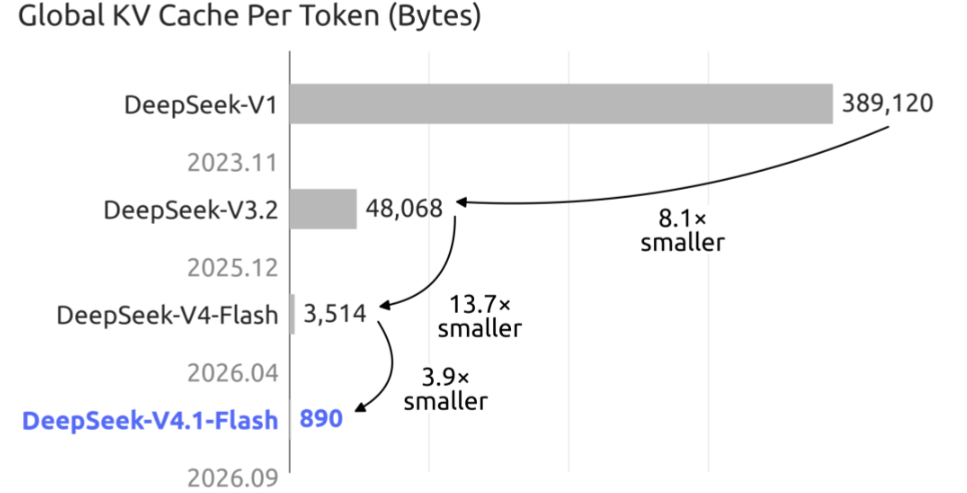
In addition, the new generation model significantly reduces the size of KV Cache. Compared with the previous generation model, the demand for HBM is reduced to 1/4, and the demand for SSD is reduced to 1/8.
In Agent usage scenarios, cache hit costs often account for a relatively high proportion. The compression of KV Cache greatly reduces the usage cost of Agent-type tasks.
The figure shows DeepSeek's continuous progress in reducing context storage. Compared with the first-generation model, the KV Cache is 1/437 of the original.
DeepSeek V4.1 Flash is now available on the DeepSeek API simultaneously, with native multimodal support. Simply change the model name to deepseek-flash to call the latest V4.1 Flash model.
The old version models V4 Flash and V4 Flash Vision Exp are now offline. For compatibility considerations, the model names deepseek-v4-flash and deepseek-v4-flash-vision-exp will be temporarily routed to V4.1 Flash.
Meanwhile, after testing from multiple parties, V4.1 Flash has comprehensively surpassed V4 Pro in all indicators including performance, cost, speed, and total time. Therefore, the official plan is to gradually take the V4 Pro model offline. After 12:00 Beijing Time on September 14, 2026, until the future launch of V4.1 Pro, user requests accessing deepseek-v4-pro will all be routed to V4.1 Flash and billed at the V4.1 Flash unit price.
Tencent (WorkBuddy, CodeBuddy) and OpenCode, as official partners, have now fully integrated DeepSeek V4.1 Flash.
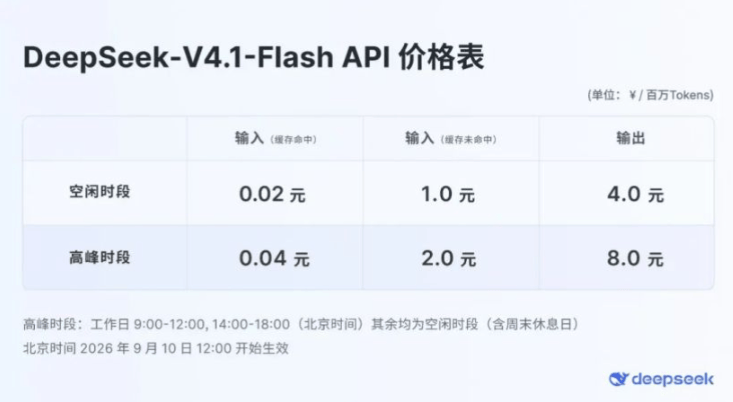
Thanks to the innovation in model architecture, DeepSeek V4.1 Flash can serve more users at a lower cost. Therefore, the official pricing for V4.1 Flash has been reduced accordingly.
At the same time, in order to allocate resources more reasonably, DeepSeek V4.1 Flash still adopts peak-valley pricing, with off-peak prices at half of peak-hour prices, encouraging users to adjust task timing based on actual usage. The new prices take effect from 12:00 on September 10, 2026.
Related Products

TWP16 P-Band Tropospheric Wind Profile Radar
China Huayun Meteorological Technology Group Co., Ltd.
KJD127(A) Mining Explosion-Proof and Intrinsically Safe Computer
Taiyuan Xiangming Intelligent Control Technology Co., Ltd.
G.652.D Wavelength-extended Non-dispersion Shifted Single-mode Optical Fiber
HONGAN GROUP CO., LTD.
Industrial and Commercial Point-Type Gas Detector
Jinan Benan Technology Development Co., Ltd.
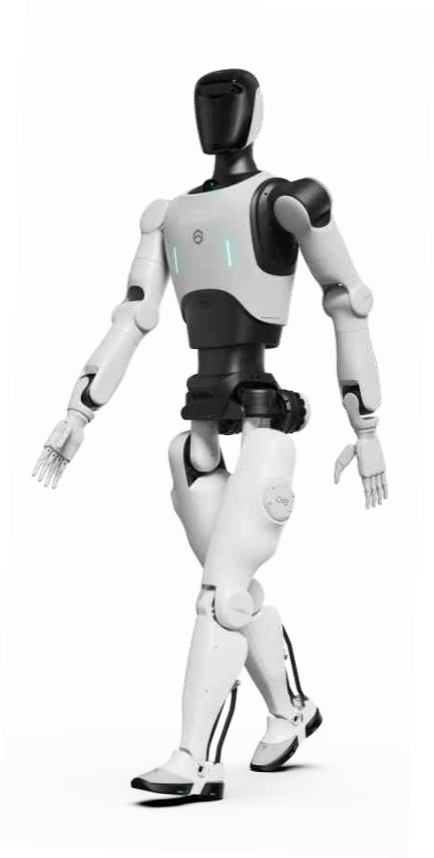
D12 Humanoid Robot
Automation Research Institute Co., Ltd. of China South Industries Group Corporation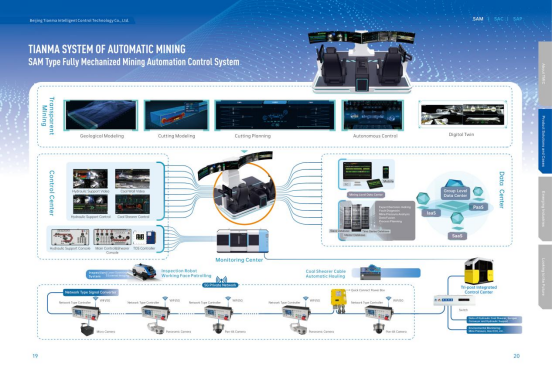
Comprehensive Mining Automation Control System
Beijing Tianma Intelligent Control Technology Co., Ltd.
20 Inch 1600*900 Full HD 60Hz TFT LED Monitor with VGA and DP Interfaces for Desktop Computers-Business Use
Guangzhou Zanying Optoelectronics Technology Co., Ltd.